


 Drupal CMS ラボ 編集部


この記事は Dries Buytaert 氏の公式ブログ「dri.es」の翻訳記事です。Driesブログの記事一覧よりすべての翻訳記事をご覧いただけます。
12種類のLLM(ローカル動作10種・クラウドベース2種)をテストし、画像のalt-text生成精度を評価しました。
私のウェブサイトには1万枚の写真があります。そのうち約9,000枚にaltテキストがありません。それを誇りに思っているわけではなく、長い間ずっと気になっていました。
ブログを始めた約20年前、altテキストのことはあまり考えていませんでした。時間が経つにつれ、スクリーンリーダーに頼る視覚障害者にとっての重要性を認識するようになりました。
この5年以上、新しくアップロードするすべての画像にaltテキストを丁寧に追加してきました。しかしそれでカバーできるのは約1,000枚に過ぎず、古い写真のほとんどには説明文がないままです。
9,000件のaltテキストを手作業で書くのは気が遠くなる話です。もちろんAIなら格段に早くできますが、品質は十分でしょうか?
それを確かめるために、12種類の大規模言語モデル(LLM)をテストしました。ローカル動作10種とクラウドベース2種です。精度を検証し、正確なaltテキストを生成できるかどうかを評価することが目的でした。
要約すると、予想通りクラウドモデル(GPT-4o・Claude Sonnet 3.5)がAグレードのパフォーマンスでベンチマークを打ち立てました(とはいえ100%完璧ではありません)。私はプライバシー・コスト・オフライン利用の観点からローカルモデルを好みます。ローカルの選択肢の中では、LlamaシリーズとMiniCPM-Vが最も優れた結果を示しました。この2つはともにBグレードを獲得しており、安定して機能しますが重要な詳細を見落とすことがあります。
こうした悩みを抱えているのは私だけではないはずです。膨大な数のaltテキスト未設定画像を抱えている人や組織は多いでしょう。自分のブログの問題を解決しながら、学んだことをシェアしていきたいと思っています。このブログ記事はその第一歩です。今後の投稿はメールまたはRSSで購読できます。
評価したモデル
12種類のAIモデルでaltテキスト生成をテストしました。9種は32GBのRAMを搭載した自分のMacBook Proで、1種はより大容量のRAMを搭載した別のマシンで(友人でDrupalの長年のコントリビューターであるJeremy Andrews氏のご協力に感謝します)、残りの2種はクラウドベースのサービスです。
以下の表にテストしたモデルの一覧を示します。論文へのリンク・リリース日・パラメータ数(10億単位)・メモリ要件・アーキテクチャの詳細などを掲載しています:
| # | モデル | 年 | タイプ | ビジョンエンコーダー | 言語エンコーダー | サイズ | RAM | 環境 |
|---|---|---|---|---|---|---|---|---|
| 1 | VIT-GPT2 | 2021 | 画像→テキスト | ViT (Vision Transformer) | GPT-2 | 0.4B | ~8GB | ローカル(Dries) |
| 2 | Microsoft GIT | 2022 | 画像→テキスト | Swin Transformer | Transformer Decoder | 1.2B | ~8GB | ローカル(Dries) |
| 3 | BLIP Large | 2022 | 画像→テキスト | ViT | BERT | 0.5B | ~8GB | ローカル(Dries) |
| 4 | BLIP-2 OPT | 2023 | 画像→テキスト | CLIP ViT | OPT | 2.7B | ~8GB | ローカル(Dries) |
| 5 | BLIP-2 FLAN-T5 | 2023 | 画像→テキスト | CLIP ViT | FLAN-T5 XL | 3B | ~8GB | ローカル(Dries) |
| 6 | MiniCPM-V | 2024 | マルチモーダル | SigLip-400M | Qwen2-7B | 8B | ~16GB | ローカル(Dries) |
| 7 | LLaVA 13B | 2024 | マルチモーダル | CLIP ViT | Vicuna 13B | 13B | ~16GB | ローカル(Dries) |
| 8 | LLaVA 34B | 2024 | マルチモーダル | CLIP ViT | Vicuna 34B | 34B | ~32GB | ローカル(Dries) |
| 9 | Llama 3.2 Vision 11B | 2024 | マルチモーダル | Custom Vision Encoder | Llama 3.2 | 11B | ~20GB | ローカル(Dries) |
| 10 | Llama 3.2 Vision 90B | 2024 | マルチモーダル | Custom Vision Encoder | Llama 3.2 | 90B | ~128GB | ローカル(Jeremy) |
| 11 | OpenAI GPT-4o | 2023 | マルチモーダル | Custom Vision Encoder | GPT-4 | >150B | — | クラウド |
| 12 | Anthropic Claude 3.5 Sonnet | 2024 | マルチモーダル | Custom Vision Encoder | Claude 3.5 | >150B | — | クラウド |
画像→テキストモデルの仕組み(30秒でわかる)
LLMにはさまざまな形態がありますが、今回は画像→テキストモデルとマルチモーダルモデルに焦点を当てました。どちらのタイプも画像を分析してテキストを生成でき、画像の説明文の生成や、画像に関する質問への回答ができます。
画像→テキストモデルはビジョンエンコーディングと言語デコーディングの2ステップで処理します:
- ビジョンエンコーディング:まず、モデルが画像をパッチ(「パズルのピース」のようなもの)に分割します。パッチは視覚的な特徴を要約した埋め込み(embeddings)と呼ばれる数値表現に変換されます。次に、アテンション機構が最も重要なパッチ(例:猫の輪郭や毛並みを捉えたピース)を抽出し、重要度の低い部分(例:青空だけのピース)を除外します。
- 言語デコーディング:最も重要な視覚的特徴を要約したら、言語モデルを使ってそれらを言葉に変換します。このステップで実際のテキスト(画像キャプションやQ&Aの回答)が生成されます。
簡単に言うと、ビジョンエンコーダーが画像を「見て」、言語エンコーダーがそれを「説明する」というわけです。
上の表を見ると、各行でビジョンエンコーダー(例:ViT・CLIP・Swin)と言語エンコーダー(例:GPT-2・BERT・T5・Llama)がペアになっていることがわかります。
より詳しい解説については、Sebastian Raschka氏の記事Understanding Multi-modal LLMsをおすすめします。画像エンコーダーの仕組みも丁寧に説明されており、とても素晴らしい内容です!
AIモデルの比較
9種類の異なるローカルモデルを使って画像のaltテキストを生成するPythonスクリプトを書きました。GitHubリポジトリで公開しています。モデルのインストール・実行・altテキストの生成を自動で行います。Hugging FaceとOllamaの両方をサポートしており、新しいモデルが登場しても簡単に拡張できる設計になっています。
スクリプトは以下のように実行できます:
$ ./caption.py ./test-images/image-1.jpg初回実行時にすべてのモデルがダウンロードされますが、かなりのディスク容量と通信量が必要です。モデルデータのダウンロードは50GB以上になる見込みです。
スクリプトはJSON形式で結果を出力するため、プログラムへの統合や分析が簡単です。出力例を示します:
  {
  "image": "test-images/image-1.jpg",
  "alt-texts": {
  "vit-gpt2": "A city at night with skyscrapers and a traffic light on the side of the street in front of a tall building.",
  "git": "A busy city street is lit up at night, with the word qroi on the right side of the sign.",
  "blip": "This is an aerial view of a busy city street at night with lots of people walking and cars on the side of the road.",
  "blip2-opt": "An aerial view of a busy city street at night.",
  "blip2-flan": "An aerial view of a busy street in tokyo, japanese city at night with large billboards.",
  "minicpm-v": "A bustling cityscape at night with illuminated billboards and advertisements, including one for Michael Kors.",
  "llava-13b": "A bustling nighttime scene from Tokyo's famous Shibuya Crossing, characterized by its bright lights and dense crowds of people moving through the intersection.",
  "llava-34b": "A bustling city street at night, filled with illuminated buildings and numerous pedestrians.",
  "llama32-vision-11b": "A bustling city street at night, with towering skyscrapers and neon lights illuminating the scene."
  }
  }
テスト画像
スクリプトが完成したので、1万枚の写真の中からいくつかを選んでテストしました。全部一度にではなく、モデルを惑わせたり挑戦させたりしそうな非標準的な写真を5枚選びました。単純なポートレートや風景写真ではなく、AIが苦手そうな要素を含む写真です。
1枚はボストンのイザベラ・スチュワート・ガードナー美術館で撮影した空の金縁フレームの写真です。そのフレームにはかつて、1990年に起きた美術史上最大級の盗難事件で奪われた傑作が飾られていました。空のフレームとして認識されるか、それとも絵が入っているフレームと勘違いされるかを確かめたかったのです。
別の1枚は昨夏バーモントで撮影したウェイクボーダーの写真です。彼は主役ですが、フレームの中では比較的小さく写っています。モデルが彼をメインの被写体として認識できるかどうかが気になりました。
また別の1枚は、暗くも居心地の良い雰囲気の中でバックギャモンゲームが設置されている写真です。部分的にしか見えないオブジェクトを認識し、シーンの雰囲気を伝えられるかを確かめたいと思いました。
公平なテストのため、すべての画像からEXIFメタデータを取り除きました。埋め込まれたキャプション・GPS座標・その他モデルの推測を助けかねない情報を排除するためです。
確かに、5枚というテストセットは小さいです。ただし、さらなる評価に向けて上位モデルを絞り込むには十分です。12種のモデルが各写真にaltテキストを生成するため、合計60件のaltテキストを手動で評価しなければならず、公平かつ正確に行うのはかなり骨の折れる作業でした。今のところこの5枚で、弱いモデルをふるい落として優れた2〜3つのLLMを特定するには十分です。
次に、5枚の写真それぞれの詳細な結果を紹介します。内容が多いので、まとめまで読み飛ばしていただいても構いません。
テスト画像1:渋谷スクランブル交差点(東京)
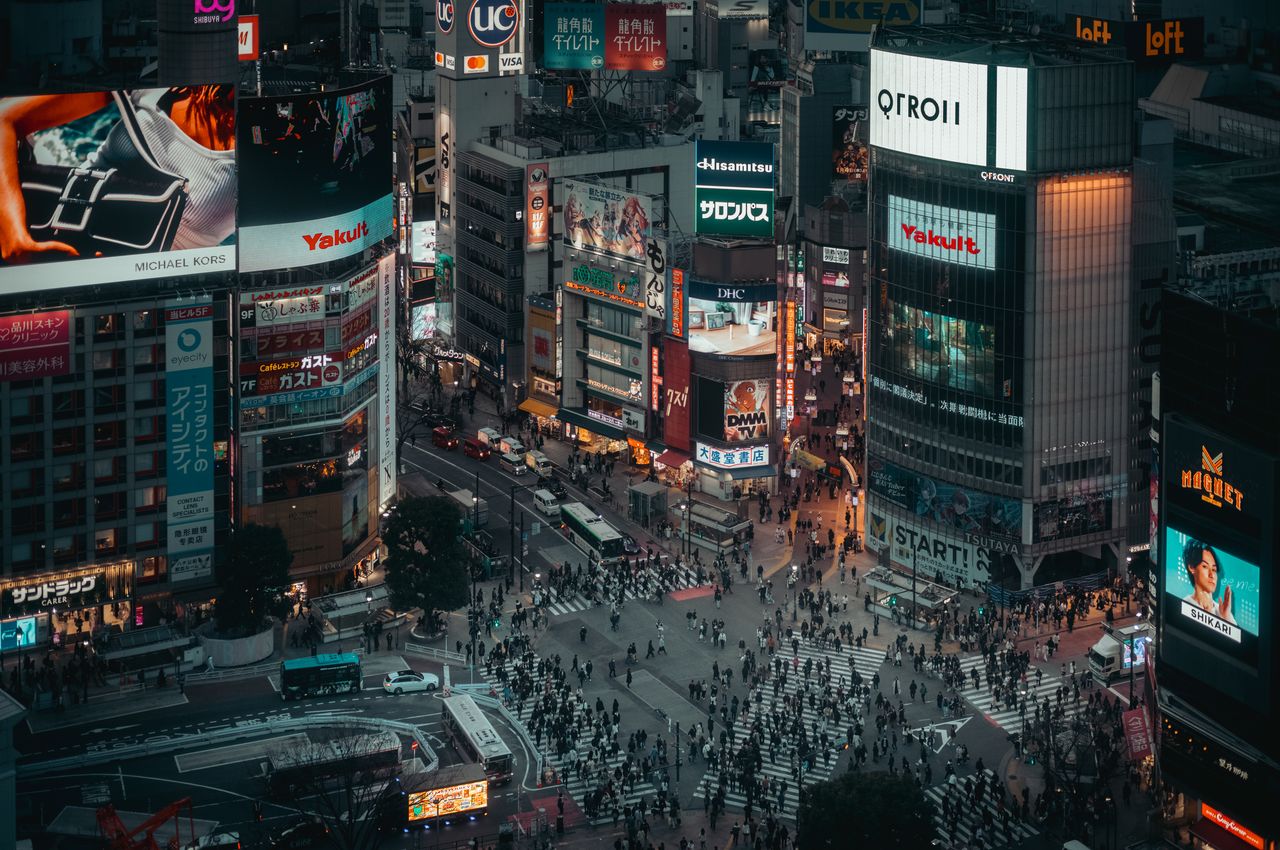
ベンチマークLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| GPT-4o | A vibrant city intersection with crowds crossing, surrounded by illuminated billboards and towering buildings, likely Shibuya, Tokyo. | A |
| Claude | Hundreds of people cross Tokyo's famous Shibuya intersection as neon signs light up the surrounding skyscrapers. | A |
ローカルLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| VIT-GPT2 | A city at night with skyscrapers and a traffic light on the side of the street in front of a tall building. | F |
| GIT | A busy city street is lit up at night, with the word qroi on the right side of the sign. | E |
| BLIP | This is an aerial view of a busy city street at night with lots of people walking and cars on the side of the road. | D |
| BLIP-2 with OPT | An aerial view of a busy city street at night. | E |
| BLIP-2 with FLAN | An aerial view of a busy street in Tokyo, Japanese city at night with large billboards. | E |
| LLaVA (13B) | A bustling nighttime scene of Tokyo's Shibuya Crossing, with neon lights and people walking across the intersection. | A |
| LLaVA (34B) | A bustling city street at night, with illuminated buildings and numerous pedestrians. | C |
| MiniCPM-V | A bustling cityscape at night with various advertisements, including one for Michael Kors and another for Yakult. | C |
| Llama 3.2 Vision (11B) | A bustling city street at night, with numerous billboards and advertisements lining the buildings. | C |
| Llama 3.2 Vision (90B) | A bustling city street with many people and buildings. | D |
テスト画像2:イザベラ・スチュワート・ガードナー美術館(ボストン)
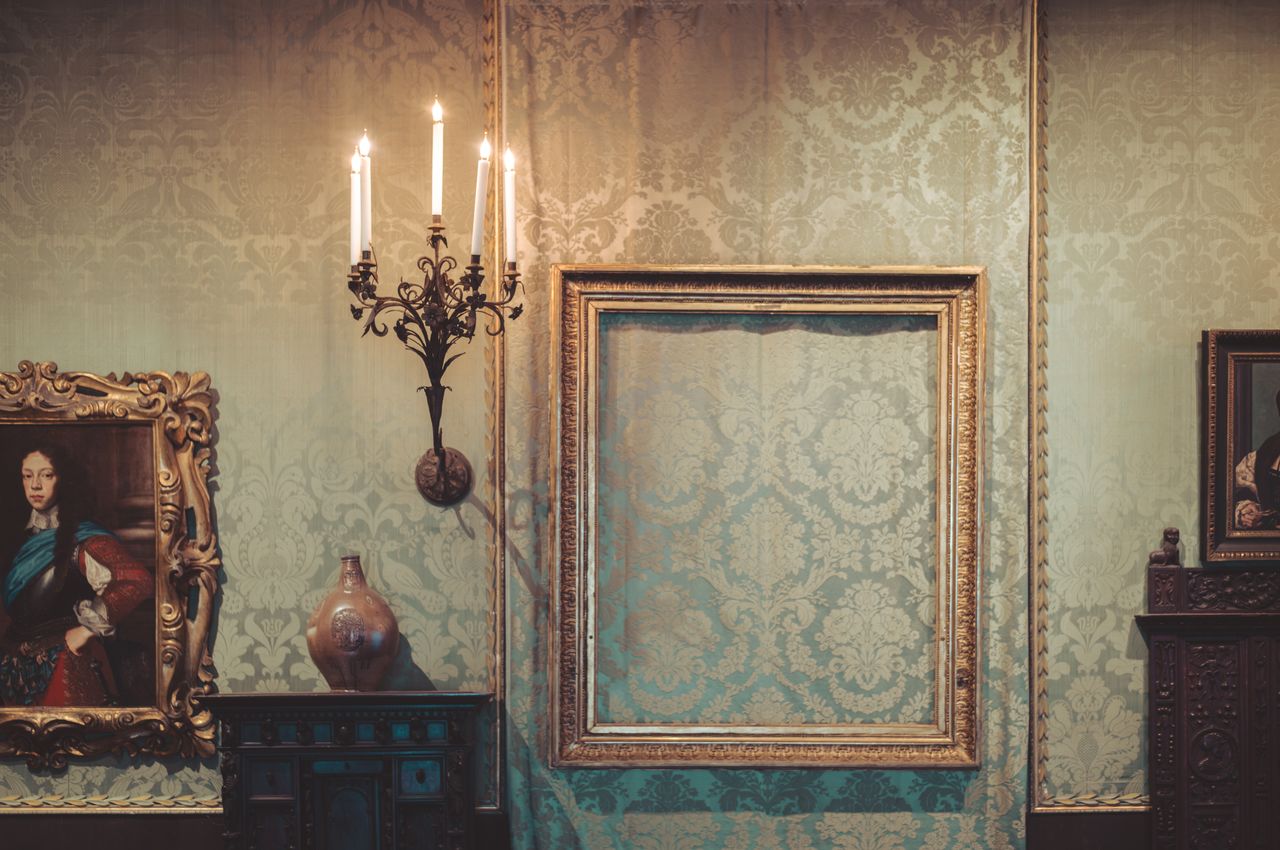
ベンチマークLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| GPT-4o | Elegant wallpaper, an empty gold frame, candelabra, and framed painting in a classic room. | B |
| Claude | Ornate Victorian room with damask wallpaper, candelabra, and gold frames on wall. | B |
ローカルLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| VIT-GPT2 | A living room with a mirror, candles, and a vase of flowers on a table in front of a mirror. | F |
| GIT | A picture frame is hanging on a wall next to a vase and a vase with the word tulips on it. | E |
| BLIP | A room with a painting on the wall and two vases on the table in front of it. | E |
| BLIP-2 with OPT | A room with a painting on the wall, a picture frame, and a chandelier. | C |
| BLIP-2 with FLAN | A room with a painting on the wall and a couple of framed pictures hanging on the wall next to it. | D |
| LLaVA (13B) | An empty wall with ornate decorations, including candlesticks and framed artwork, suggesting a formal or historical setting. | D |
| LLaVA (34B) | An ornate room with framed pictures on the wall, a chandelier hanging from the ceiling, and a fireplace mantel adorned with decorative items. | E |
| MiniCPM-V | A room with ornate wallpaper, candlesticks and framed portraits of historical figures is displayed. | |
| Llama 3.2 Vision (11B) | An empty gold frame on a wall with ornate wallpaper, surrounded by other decorative items. | A |
| Llama 3.2 Vision (90B) | An ornate room with a gold frame, a painting of a man, and a vase on a table. | B |
テスト画像3:ウェイクボーディング(バーモント州、米国)
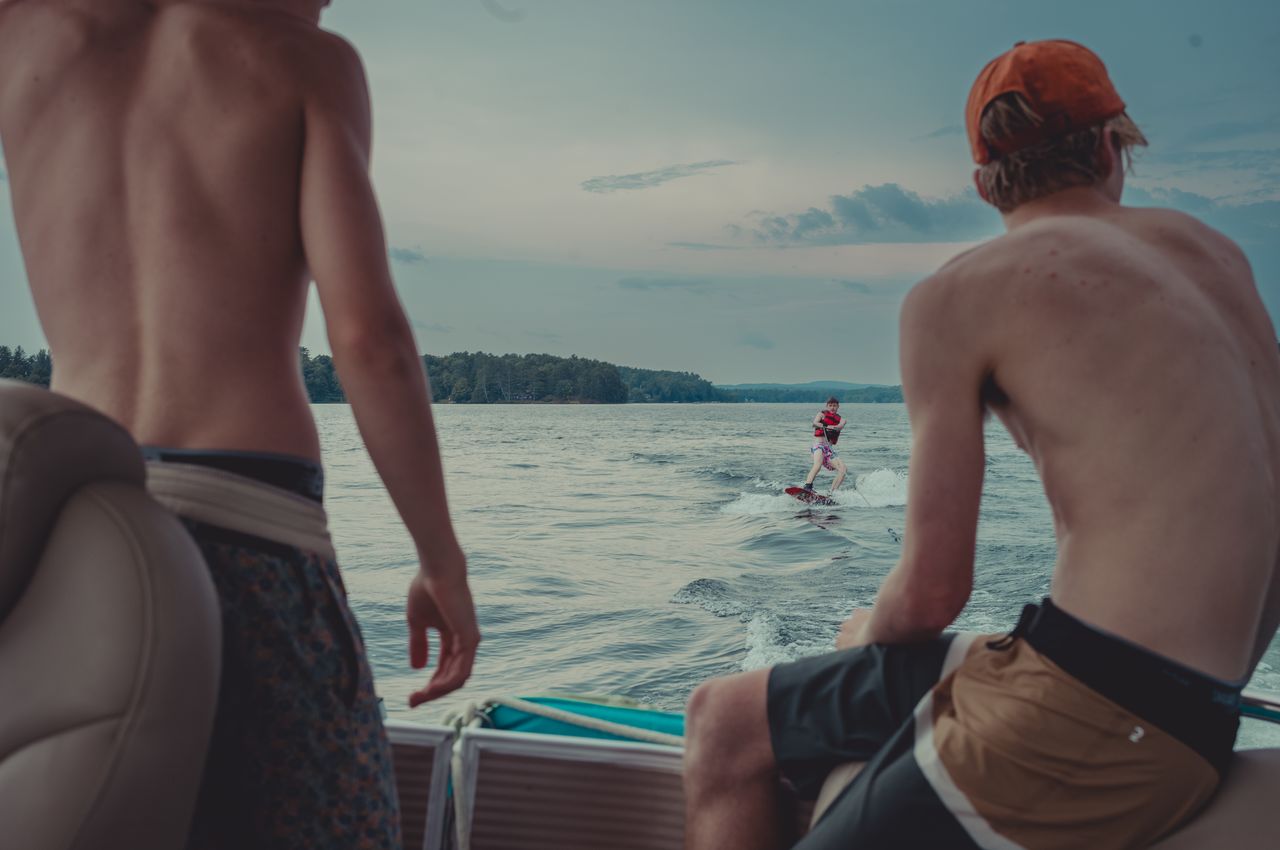
ベンチマークLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| GPT-4o | Two shirtless boys on a boat watch a person wakeboarding in the distance on a cloudy day. | A |
| Claude | People watching from a boat as a person is wakeboarding on a lake with a wooded shoreline. | B |
ローカルLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| VIT-GPT2 | A man standing on top of a boat next to another man holding a surfboard in one hand and a surfboard in the other. | E |
| GIT | Two men are in a boat, one of them is wearing an orange hat and the other is wearing an orange hat. | D |
| BLIP | There are two men riding on the back of a boat in the water, one of them is on a surfboard and the other is on a board. | D |
| BLIP-2 with OPT | Three young men sitting on the back of a boat. | D |
| BLIP-2 with FLAN | A group of people sitting on a boat watching a man ride a surfboard in the middle of the water. | C |
| LLaVA (13B) | Two shirtless men on a boat, watching another man surfing in the water. | B |
| LLaVA (34B) | Two shirtless men on a boat, watching another person water skiing. | B |
| MiniCPM-V | Two shirtless men on a boat watch as another person water skis away from them, with trees and sky visible across the lake behind him. | B |
| Llama 3.2 Vision (11B) | Two shirtless men on a boat watching people wakeboarding or surfing behind it. | B |
| Llama 3.2 Vision (90B) | Two men on a boat watching another man wakeboarding. | A |
テスト画像4:ドロミテ登山(イタリア)
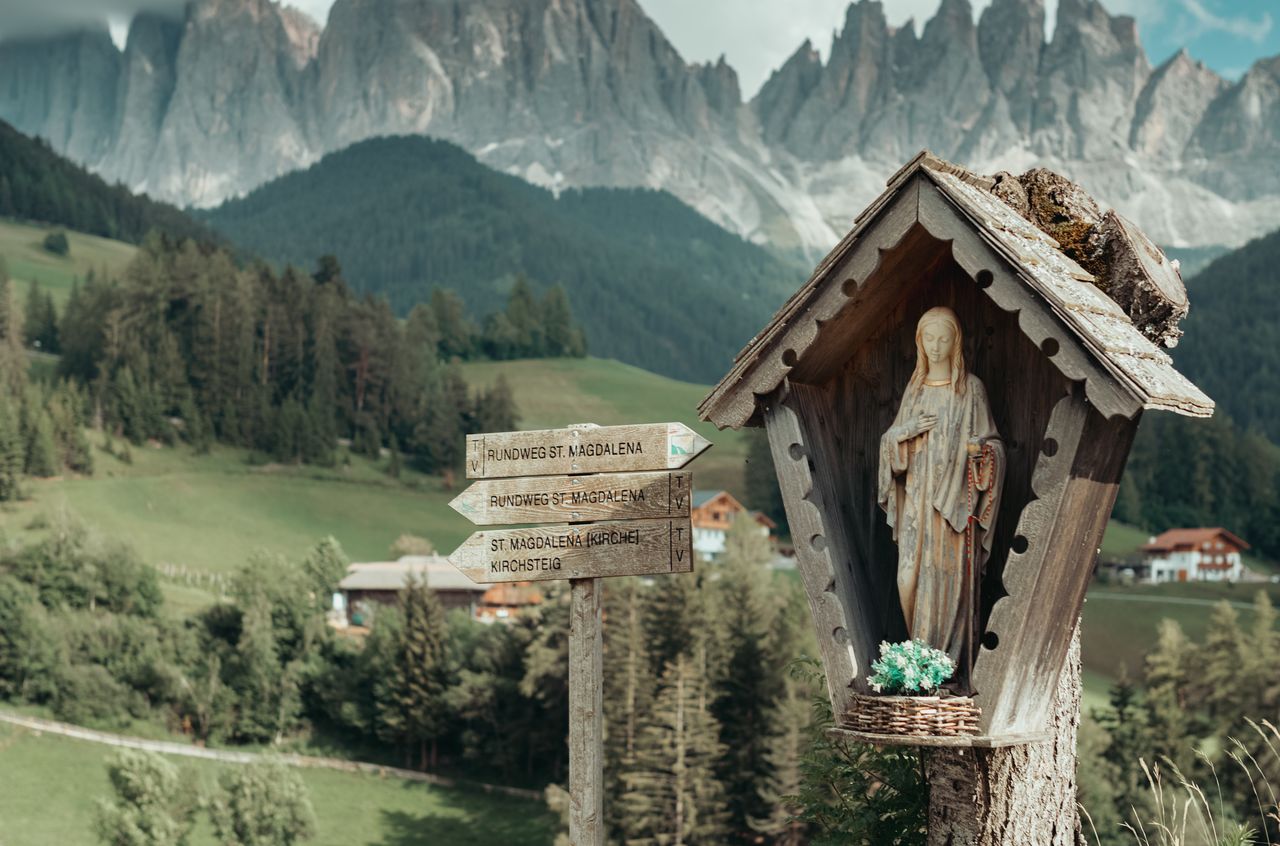
ベンチマークLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| GPT-4o | A wooden shrine with a statue of Mary and directional signs, set against mountains and green hills. | A |
| Claude | Wooden shrine of St. Magdalena with trail signs in the Dolomites mountains of Italy. | A |
ローカルLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| VIT-GPT2 | A bird perched on top of a wooden post in front of a mountain range with a view of a mountain range and mountains. | F |
| GIT | A wooden sign in front of a mountain with a statue on it that says "Meise museum" on the top. | D |
| BLIP | There is a birdhouse with a statue on top of it in the middle of a field with trees and mountains in the background. | D |
| BLIP-2 with OPT | A statue of Mary on a wooden post in the middle of a field with mountains in the background. | B |
| BLIP-2 with FLAN | A statue of the Virgin Mary sits on top of a wooden post in the middle of a mountain. | C |
| LLaVA (13B) | A picturesque scene of a small wooden chapel with a statue of Jesus, set against a backdrop of majestic mountains and lush greenery. | C |
| LLaVA (34B) | A wooden shrine with religious iconography, surrounded by alpine scenery and signposts. | B |
| MiniCPM-V | A wooden shrine with a statue of Mary and several directional signs pointing to various locations such as Kirchsteig, Magdalena, St. | B |
| Llama 3.2 Vision (11B) | A wooden shrine with a statue of Mary and a signpost in front of mountains. | A |
| Llama 3.2 Vision (90B) | A statue of Mary in a wooden shrine with a signpost pointing to various locations, including Rundweg St. | B |
テスト画像5:キャンドルの明かりでバックギャモン
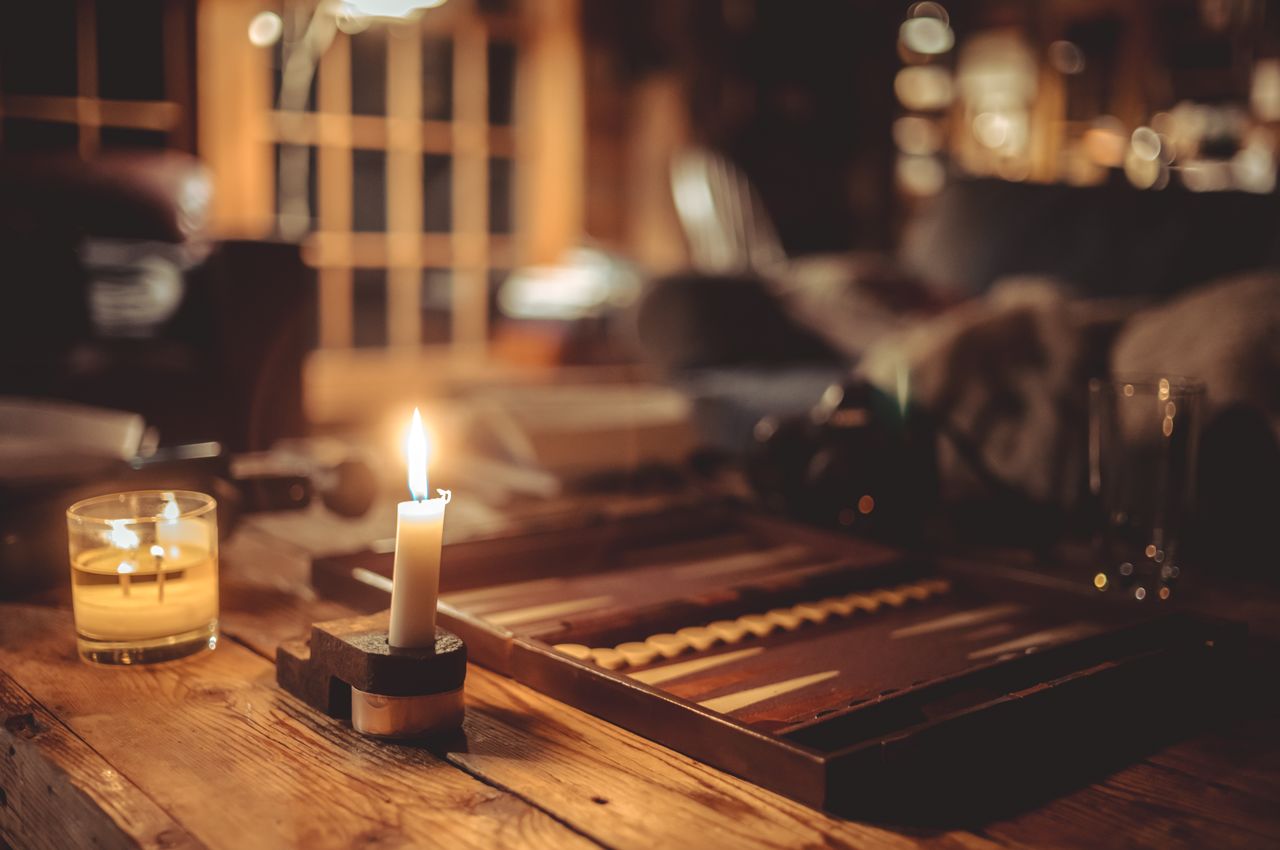
ベンチマークLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| GPT-4o | A cozy, dimly lit room with a candle on a wooden table, next to a backgammon board, creating a warm, rustic ambiance. | B |
| Claude | Two candles light up a game board for backgammon on a wooden table at night. | A |
ローカルLLM:
| モデル | 説明文 | グレード |
|---|---|---|
| VIT-GPT2 | A candle is lit on a wooden table in front of a fire place with candles and other items on top of it. | E |
| GIT | Two candles are lit next to each other on a table, one of them is lit up and the other is lit up. | D |
| BLIP | There is a lit candle sitting on top of a wooden table next to a game board and a glass of wine on the table. | D |
| BLIP-2 with OPT | A candle sits on top of a wooden table. | C |
| BLIP-2 with FLAN | A candle sits on a wooden table next to a backgammon board and a glass of wine. | D |
| LLaVA (13B) | A cozy indoor setting with candles, a guitar, and a warm ambiance. | D |
| LLaVA (34B) | A candlelit wooden table with musical instruments and a cozy ambiance. | C |
| MiniCPM-V | A dimly lit room with candles and backgammon pieces on a wooden table, creating an atmosphere of relaxation or leisure activity. | A |
| Llama 3.2 Vision (11B) | A dimly lit room with a wooden table, featuring a backgammon board and two candles. | A |
| Llama 3.2 Vision (90B) | A candle and backgammon board on a wooden table. | B |
モデルの精度
各説明文の評価には構造化された主観的なスコアリングシステムを用いました。各画像について、AIが認識して説明に含めるべき最も重要なオブジェクトを2〜3つ特定しました。また、視覚障害者にとって重要な写真の雰囲気を捉えられているかも評価しました。さらに、繰り返し・文法エラー・ハルシネーション(事実と異なる詳細の捏造)については減点しました。各altテキストは0〜5点で採点し、AからFのレター評価に換算しました。
| モデル | 繰り返し | ハルシネーション | 雰囲気 | 平均スコア | グレード |
|---|---|---|---|---|---|
| VIT-GPT2 | 多い | 多い | 不良 | 0.4/5 | F |
| GIT | 多い | 多い | 不良 | 1.6/5 | D |
| BLIP | 多い | 多い | 不良 | 1.8/5 | D |
| BLIP2 w/OPT | まれ | 時々 | 普通 | 2.6/5 | C |
| BLIP2 w/FLAN | まれ | 時々 | 普通 | 2.2/5 | D |
| LLaVA 13B | なし | 時々 | 良好 | 3.2/5 | C |
| LLaVA 34B | なし | 時々 | 良好 | 3.2/5 | C |
| MiniCPM-V | なし | なし | 良好 | 3.8/5 | B |
| Llama 11B | なし | まれ | 良好 | 4.4/5 | B |
| Llama 90B | なし | まれ | 良好 | 3.8/5 | B |
| GPT-4o | なし | なし | 良好 | 4.8/5 | A |
| Claude 3.5 Sonnet | なし | なし | 良好 | 5/5 | A |
クラウドベースモデルのGPT-4oとClaude 3.5 Sonnetは、5枚の小規模テストでほぼ完璧なパフォーマンスを発揮し、大きなエラー・ハルシネーション・繰り返しはなく、雰囲気の捉え方も優れていました。
ローカルモデルの中では、LlamaシリーズとMiniCPM-Vが最も優れた結果を示しました。
説明文の繰り返しはスクリーンリーダーのユーザーを苛立たせます。VIT-GPT2・GIT・BLIP・BLIP2などの初期モデルは頻繁に繰り返しが生じるため、実用には不適切です。
ハルシネーションは私が深刻な問題だと考えている点です。存在しないオブジェクトや行動を説明することは、視覚障害者のユーザーを誤解させ、信頼を損ないます。最も優れたローカルモデルの中では、MiniCPM-Vはハルシネーションを起こしませんでしたが、Llama 11BとLlama 90Bはそれぞれ1回ずつ誤りを犯しました。Llama 90Bは美術館のキャビネットをテーブルと誤認識し、Llama 11Bはウェイクボーダーが1人ではなく複数人いると説明しました。大きな誤りではありませんが、やはり残念です。
雰囲気を捉えることは、視覚障害者が画像をより豊かに理解するために欠かせません。初期モデルはこの点で苦労していましたが、最近のモデルはすべてよく対応できていました。LLaVAの両バリアントとMiniCPM-Vを含みます。
実用面から見ると、Llama 11BとMiniCPM-Vは32GB RAMのラップトップでスムーズに動作しましたが、Llama 90Bはより多くのメモリが必要でした。つまり、追加テストの最有力候補はLlama 11BとMiniCPM-Vということになります。
考えられる次のステップ
結果を踏まえると、難しい問いが浮かびます。「B」レベルのaltテキストは、何もないよりはましでしょうか?人間が書いたaltテキストも完璧ではないものが多いでしょう。ローカルモデルが「A」グレードになるまで待つべきか、それとも不完全な説明文でも何もないよりはましなのか?
考えられる次のステップが4つあります:
- AIの出力を組み合わせる——同じ画像を複数のモデルで処理し、結果をマージしてより正確な説明文を作ろうとする方法。
- 待ってアップグレードする——現時点では最善のローカルモデルを使い、AI生成の
altテキストをデータベースにタグ付けしておき、より優れたローカルモデルが登場する6〜12ヶ月後に再生成する方法。 - クラウドベースにする——65GBの写真をアップロードすることになっても、クラウドモデルで最高品質を得る方法。理由はうまく説明できませんし、その感覚が正当かどうかもわかりませんが、なんとなく「負けた」気がします。
- ハイブリッドアプローチ——AIで
altテキストを生成しつつ、手動でレビューする方法。9,000枚ではとても現実的ではありません。間違いが多そうなaltテキストにフラグを立てる方法が必要です。LLMは信頼性の高い確信スコアを出してくれるでしょうか?
どの選択肢にもトレードオフがあります。速いが不完全なものもあれば、手間はかかるが価値があるものも。クラウドベースが一番楽ですが「負けた」気がします。より良いモデルを待つのは楽ですが、進歩が遅れます。AIの出力のマージや確信スコアの付与は手間がかかりますが、スピードと精度のバランスが取れた最善策かもしれません。
これらを組み合わせた解決策があるかもしれません。今すぐクラウドベースにして、データベースにAI生成のaltテキストをタグ付けしておき、LLMがさらに進歩する6〜12ヶ月後に再生成する、という方法です。
最終的には実用主義と信念のバランスの問題でもあります。データプライバシーとオープンソースを信じてローカルモデルにこだわるべきか、それとも視覚障害者のために最良のaltテキストを提供することでアクセシビリティを優先すべきか。ローカルファーストのアプローチは自分の価値観に合っていますが、視覚障害者のユーザー体験がその分損なわれてしまうかもしれません。
この選択肢について、今後数週間かけて検討するつもりです。皆さんならどうしますか?ぜひ意見を聞かせてください!
更新:alt-textへのAI活用についての考えは、複数のブログ記事を通じて進化してきました。最初は結局クラウドベースのLLMを選びました。次に、1枚の画像の説明文を生成・更新する自動化システムを構築しました。そして最終的に9,000枚に拡大し、その過程でAIを信頼することを学びました。
By Dries Buytaert
この記事は「Comparing local large language models for alt-text generation」(投稿日:2025-02-03)の翻訳記事です。
カテゴリ
 カテゴリ
 関連リンク


 Driesブログ記事一覧